Moonshot AI released Kimi K3.1 Pro on October 23: an open weights reasoning model with 2.8 trillion parameters (104 billion active per token) and a 1M token context. On the current Artificial Analysis Intelligence Index it is the highest scoring open weights model in the world, 13 points ahead of the next one.
It now runs uncensored on our API: an abliterated Kimi K3.1 Pro, with the refusal behaviour removed from the weights, behind the same OpenAI and Anthropic compatible key as every other model.
- API model id:
kimi-k3.1-pro-uncensored - Price: $2.50 per million input tokens and $5.00 per million output tokens, with cached input at $0.25
- Try it: the playground, or the model page
- Fallback: if it is ever unavailable, requests move to GLM 5.3 Uncensored automatically, and the response's
modelfield says which one answered
The smartest open weights model
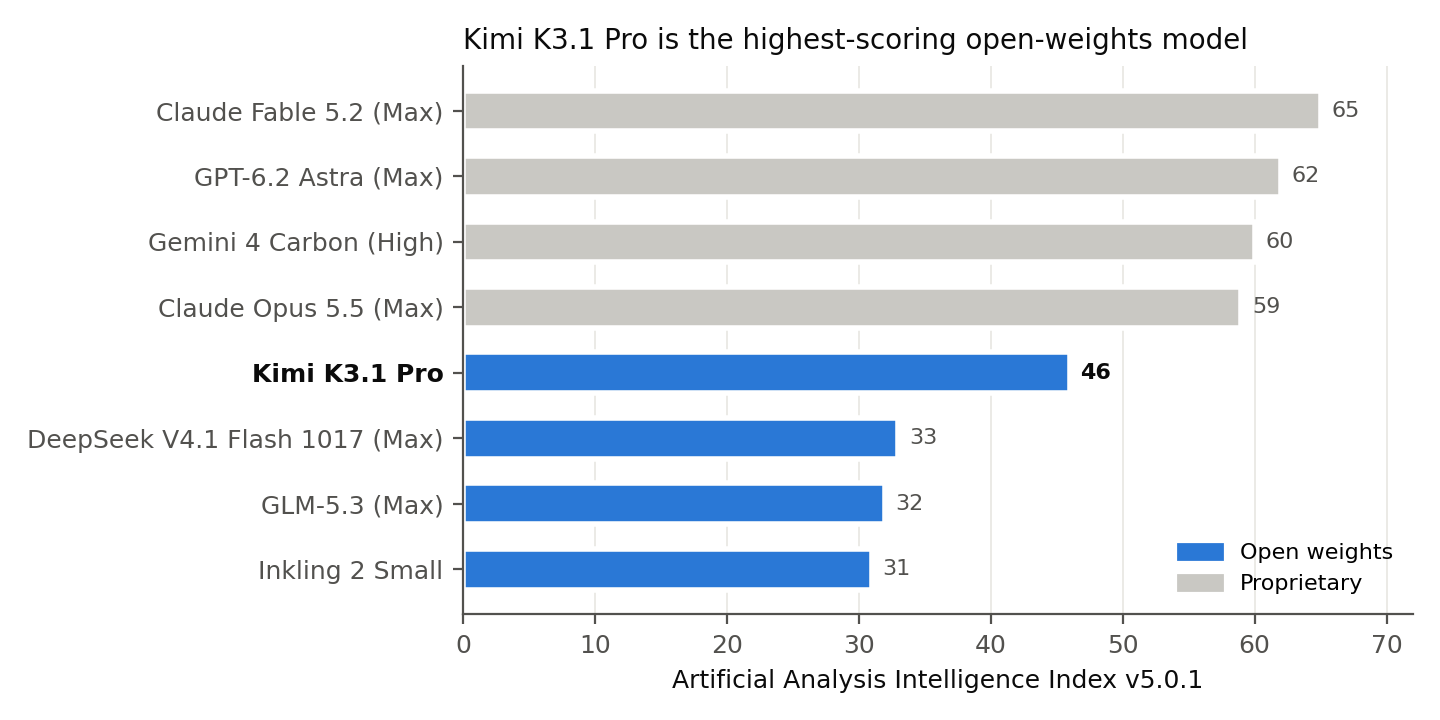
Artificial Analysis scores Kimi K3.1 Pro 46 on version 5.0.1 of its Intelligence Index, nine hard, mostly private evaluations including Terminal-Bench 4.0, HLE Diamond and AA-Briefcase. That is the top score among the open weights models it tracks:
| Model | Intelligence Index v5.0.1 | Weights |
|---|---|---|
| Claude Fable 5.2 (Max) | 65 | Proprietary |
| GPT-6.2 Astra (Max) | 62 | Proprietary |
| Gemini 4 Carbon (High) | 60 | Proprietary |
| Claude Opus 5.5 (Max) | 59 | Proprietary |
| Kimi K3.1 Pro | 46 | Open |
| DeepSeek V4.1 Flash 1017 (Max) | 33 | Open |
| GLM-5.3 (Max) | 32 | Open |
| Inkling 2 Small | 31 | Open |
The closed frontier models still lead. But among models whose weights anyone can download, nothing is close: the next three open models sit within two points of each other (33, 32 and 31), and Kimi K3.1 Pro is 13 points above them.
Reported benchmarks
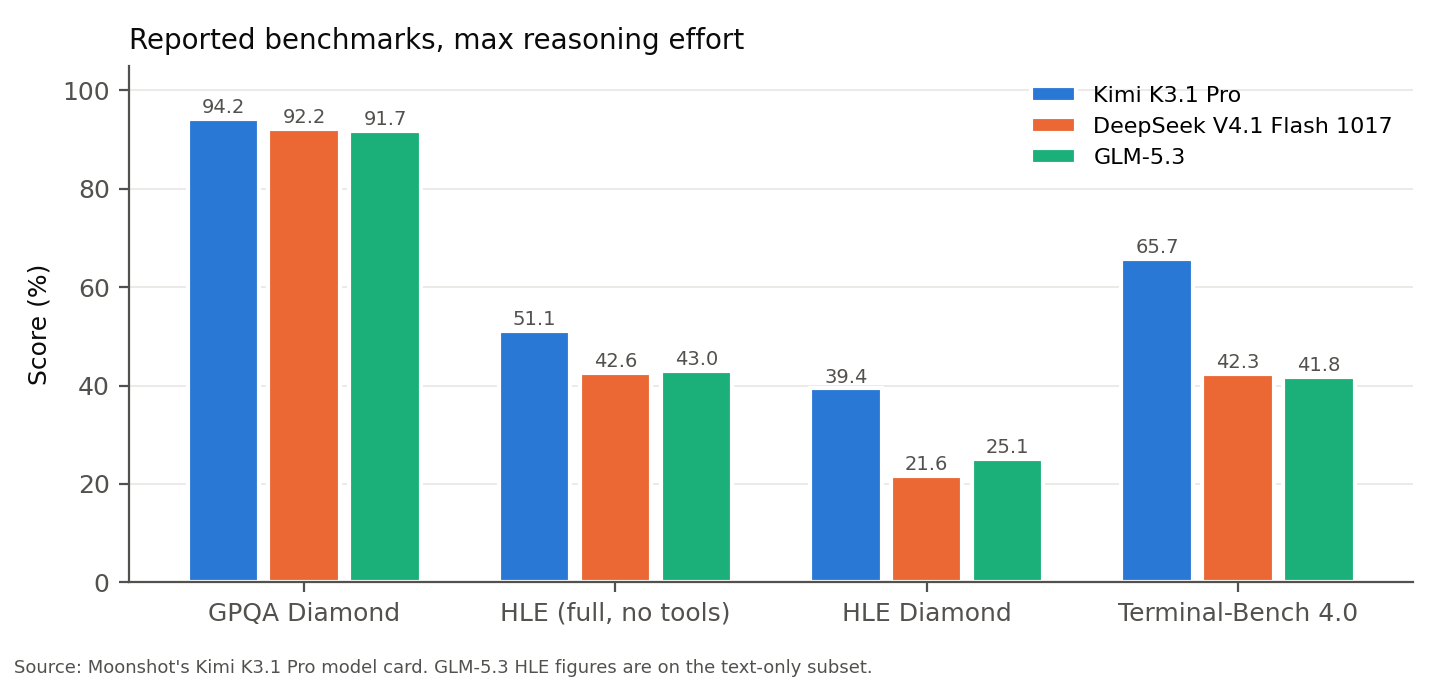
From Moonshot's model card, at maximum reasoning effort:
| Benchmark | Kimi K3.1 Pro | DeepSeek V4.1 Flash 1017 | GLM-5.3 |
|---|---|---|---|
| GPQA Diamond | 94.2 | 92.2 | 91.7 |
| Humanity's Last Exam, full set, no tools | 51.1 | 42.6 | 43.0* |
| Humanity's Last Exam, Diamond | 39.4 | 21.6 | 25.1* |
| Terminal-Bench 4.0 | 65.7 | 42.3 | 41.8 |
* GLM-5.3 on the text only subset. With tools, Kimi K3.1 Pro reaches 70.0 on the full Humanity's Last Exam. These are the vendor's numbers; the Artificial Analysis index above is independent.
What uncensoring changed
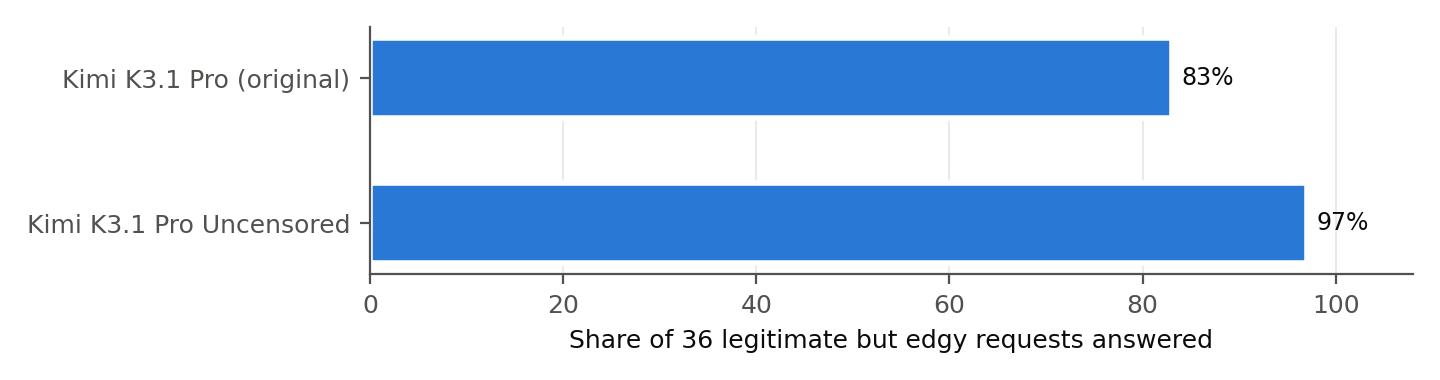
We ran the same tests on the original and the uncensored version, through the same API settings.
| Test | Original | Uncensored |
|---|---|---|
| Legitimate but edgy requests answered (36: security research, chemistry, medicine, dark fiction, finding people) | 83% | 97% |
| Multiple choice knowledge and reasoning (30 questions) | 30 / 30 | 30 / 30 |
| Single tool calls with the right function and arguments (20 cases) | – | 20 / 20 |
| Multi-step agent tasks finished (5) | 4 / 5 | 1 / 5 |
On our own leaderboard it scores 59.7, #14 of 34: the highest intelligence component of any model we rank (72.7), agentic 38, and it answers 97% of the edgy requests. Full table: rankings.
The original refuses about one request in six that has a legitimate use. The uncensored version answers nearly all of them, with no loss on our knowledge questions and clean single tool calls.
The weak spot is agent loops. On our five multi-step agent tasks, the original finished four and this uncensored version one. Most of its failures look the same: it reasons about its next step ("let me check the file first"), then ends the turn without the tool call or an answer. One shot questions are not affected. So for now we recommend it for hard questions and long reasoning, and DeepSeek V4.1 Flash 1017 Uncensored or GLM 5.3 Uncensored for agents.
Using it
from openai import OpenAI

client = OpenAI(base_url="https://api.openuncensored.com/v1", api_key="ou-...")

r = client.chat.completions.create(
    model="kimi-k3.1-pro-uncensored",
    messages=[{"role": "user", "content": "Find the race condition in this function: ..."}],
    max_tokens=16000,
)
print(r.choices[0].message.content)
Give it room to think. Kimi K3.1 Pro reasons before it answers. In our tests the first visible token arrived after
about 25 seconds and replies then streamed at about 90 tokens per second. With a small max_tokens (under a few
thousand) it can spend the whole budget thinking and return an empty answer, so set it high.
It works with any OpenAI or Anthropic client by changing the base URL, including Claude Code, Codex and OpenCode (setup), with the agent caveat above.
When to use it
- Hard problems where intelligence matters most: research questions, difficult code reviews, math, long reasoning, in one or a few turns. This is the strongest open model you can call uncensored.
- Agents and long tool loops: DeepSeek V4.1 Flash 1017 Uncensored (#1 on our leaderboard) or GLM 5.3 Flash Uncensored finish more multi-step tasks, cost far less per token and answer sooner.
- Price: Artificial Analysis lists Moonshot's own API for the original at $2.00 input and $10.00 output per million tokens. The uncensored version here costs $2.50 and $5.00.
FAQ
Is Kimi K3.1 Pro the smartest open weights model?
On the Artificial Analysis Intelligence Index v5.0.1, yes: 46, the highest of any open weights model, ahead of DeepSeek V4.1 Flash 1017 (33) and GLM-5.3 (32).
Does the uncensored version lose intelligence?
Not on knowledge: 30 of 30 on our questions for both versions, and perfect single tool calls. It does finish fewer multi-step agent tasks than the original (1 of 5 against 4 of 5 in our test), so use it for hard questions rather than long agent loops. Full numbers on the rankings.
Can I use it without an account?
Yes. Buy a prepaid key on the credits page; the key is the account.